AI "Middleman" Earns Millions Monthly? Five Questions Reveal the Truth Behind Token Arbitrage
AI "Middleman" Earns Millions Monthly? Five Questions Reveal the Truth Behind Token Arbitrage


Over the past month, the term "transit hub" has frequently appeared on many users' homepages. Some veteran crypto airdrop hunters have quietly transformed into "API transit hub" operators, engaging in token import and export services.
The so-called "transit hub" is not a new technological invention, but rather an arbitrage model based on global AI service price disparities and access barriers. Despite facing multiple challenges including privacy, security, and compliance risks, this space continues to attract numerous individuals and small teams.
So, what exactly is an "API transit hub"? How does it enable token arbitrage amid global AI price gaps and access constraints, drawing in so many individuals and small teams? Let's break it down from its essence and operational flow.
One: What Is a Transit Hub?
The core of an API transit hub lies in establishing an intermediary service layer that offers overseas AI vendors’ API tokens at lower prices and greater convenience to domestic users—earning the nickname “global token hauler.”
Its operational flow generally follows:
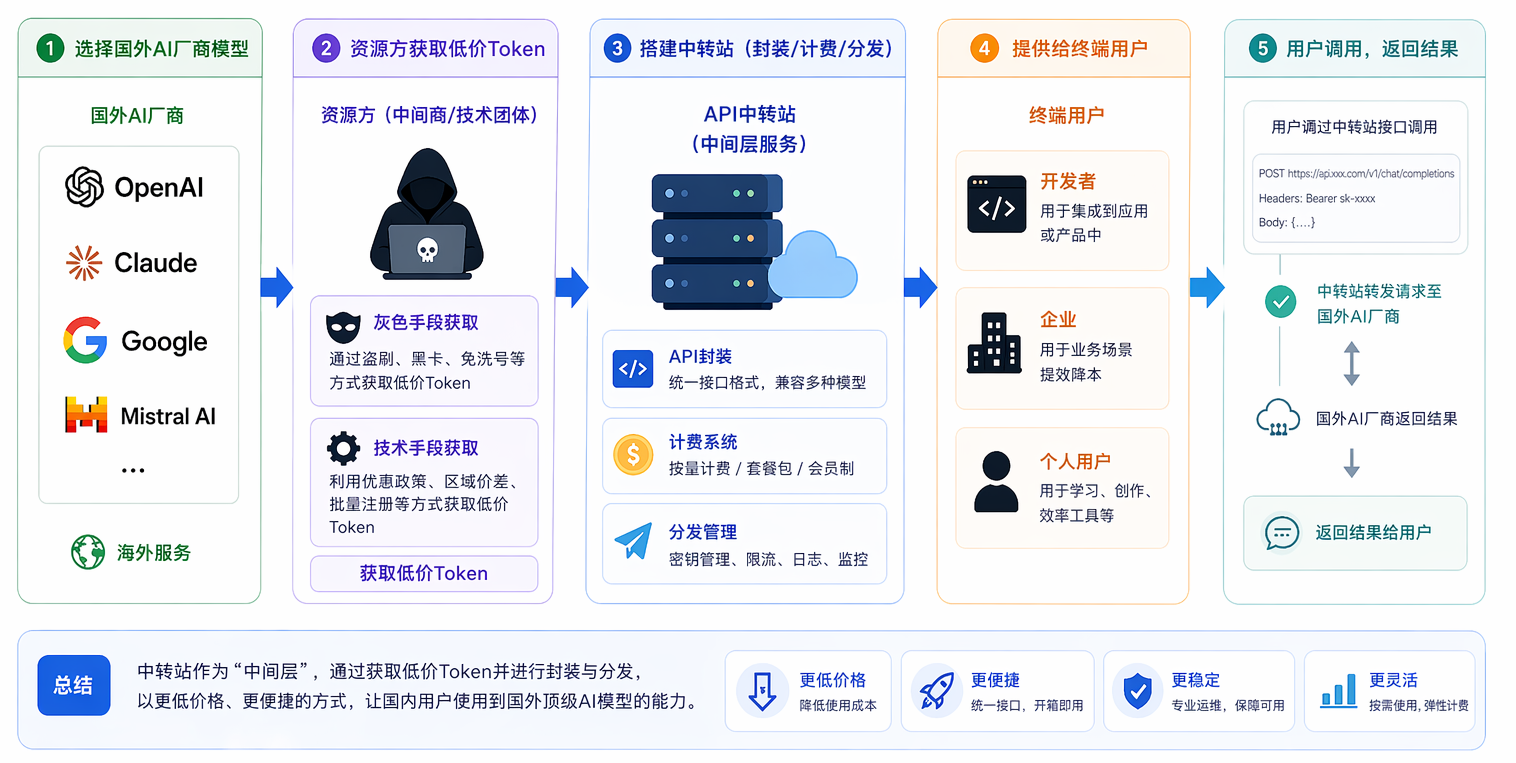
👉 Select overseas AI vendor models (e.g., OpenAI, Claude)
👉 Resource providers obtain low-cost tokens via "gray" or technical means
👉 Build a transit hub for encapsulation, billing, and distribution
👉 Deliver to end-users such as developers, enterprises, or individuals
Functionally, it acts like an “AI transshipment station”; commercially, it operates more like a liquidity intermediary in a secondary token market.
The viability of this chain hinges not on technical barriers, but on several persistent discrepancies:
• Official API pricing remains high
• Mismatch between subscription-based and API-based cost structures
• Regional differences in access and payment conditions
• Strong user demand for model capabilities, yet poor user-friendliness of official integration paths
Only when these factors converge do transit hubs find room to thrive.
Two: Why Do People Use Transit Hubs?
The surge in "token import" stems primarily from the soaring costs driven by AI’s evolving role and the persistent capability gap between domestic and foreign models.
1. High-End Models Consume Tokens Rapidly
With the maturation of desktop-grade AI agents like Codex and Claude Code, AI has truly gained the ability to perform real work—such as code assistance, video editing, financial trading, and office automation. These tasks heavily rely on high-performance large models, with costs billed per token.
Take Claude Code as an example: its official rate is approximately $5 per million tokens (~35 CNY). Intensive use for just one hour may consume tens of dollars, while heavy developers or enterprises can exceed $100 daily. This cost far exceeds many users’ expectations—even surpassing the cost of hiring junior programmers—making “how to use top-tier AI affordably” a pressing need.
2. Overseas Leading Models Hold Clear Advantages
Despite rapid progress in domestic models over the past year and their competitive pricing, overseas leaders still maintain a significant edge in complex coding tasks, toolchain coordination, long-chain reasoning, and multimodal stability.
This explains why many developers, researchers, and content teams, even aware of higher prices, continue to prioritize using OpenAI, Anthropic, or Google’s models.
In short, users aren’t necessarily seeking “transit hubs”—they simply want:
• Stronger models
• Lower prices
• Simpler access
When these three cannot be simultaneously achieved through official channels, transit hubs naturally emerge.
3. Mismatch Between Subscription and API Pricing
The rise of transit hubs is also fueled by a commonly discussed issue: subscription benefits don’t always linearly align with API billing.
A prevalent practice exists in the market: purchasing official subscriptions, team plans, enterprise credits, or other discounted resources, then packaging and reselling part of the capacity to end-users.
For instance, with OpenAI, a Plus subscription enables access to Codex services via OAuth login into OpenClaw—functionally equivalent to calling the API. The $20 monthly subscription generates roughly 26 million tokens. With output priced at $10–$12 per million, this translates to $260–$312 worth of usage. Reselling token access derived from subscriptions offers exceptional cost efficiency.
From user experiences, this route can indeed be cheaper than direct official API usage during certain periods. However, it must be emphasized that:
• This is not the official pricing model
• It does not guarantee stable, equivalent replacement of API calls
• It certainly does not imply long-term sustainability
Many see only “low cost,” but overlook that these savings often rest on unstable resources, gray-area practices, or strategic loopholes.
Three: Can You Use Transit Hubs?
Whether you can use them isn’t an absolute yes or no.
The real question is: what risks are you willing to accept?
The profit model of transit hubs appears straightforward—buy low, sell high. But upon deeper inspection, they typically involve at least three layers, each carrying distinct risks.
1. Upstream: Where Do Low-Cost Token Resources Come From?
This is the foundational layer—and the most ambiguous one.
Some resource providers acquire model call capacity at prices far below market rates through various methods, such as:
• Leveraging enterprise support programs and cloud credits
• Bulk account registration with rotation
• Re-distributing subscription rights, team accounts, or promotional resources
• In more extreme cases, involving credit card fraud or fake account creation
The source of upstream resources determines the maximum stability of the transit hub. If the supply chain itself relies on unstable or illegal methods, end users aren’t getting a bargain—they’re receiving a temporary interface that could fail at any moment.
2. Midstream: Whose Servers Process Your Data?
This is often the most overlooked issue.
When you invoke models through a transit hub, your input prompts, context, file contents, and model outputs typically pass through the hub’s own servers first.
These data hold immense value, reflecting genuine user intent, industry-specific prompts, and model output quality—useful for evaluating or fine-tuning internal models. The hub may anonymize and package this data for sale to domestic large model companies, data brokers, or academic institutions. Users pay for access while unknowingly contributing training data—turning customers into products themselves.
Recent comments by OpenClaw founder @steipete highlight this concern: https://x.com/steipete/status/2046199257430888878
Beyond data monetization, transit hubs may inject scripts into request flows (e.g., stealthily adding hidden system prompts), altering model behavior, increasing token consumption, and introducing additional security risks—especially critical in AI Agent scenarios.
3. Endpoint: Are You Getting the Premium Model You Paid For?
This is the third common risk: model downgrade or model substitution.
Users may pay for a premium model name, but the actual model invoked might not match. Simply put: for some vendors, the easiest way to cut costs isn’t optimization—it’s replacement.
For example, a user buys the flagship Opus 4.7, but the actual model used could be the mid-tier Sonnet 4.6 or lightweight Haiku. Since API formats remain compatible, ordinary users may not notice immediately.
Only when tasks grow complex do users realize “results don’t match,” “stability is poor,” or “context quality deteriorates”—but lack proof. Research testing across 17 third-party API platforms revealed that 45.83% suffer from “identity mismatch”: users pay GPT-4 prices but run cheap open-source models, with performance gaps up to 40%.
In sum, using unofficial transit hubs exposes users to data leaks, privacy breaches, service outages, model mismatches, and potential exit scams. Therefore, for sensitive operations, commercial projects, or tasks involving personal privacy, we strongly recommend using official APIs.
Four: Can This Business Be Sustained?
Despite high risks, this business hasn’t disappeared—on the contrary, it keeps evolving.
While early “token import” focused on bringing overseas models in cheaply, today’s market sees a new trend emerging: “token export.”
1. Why Do People Still Do This?
Because real demand exists, startup costs are low, and prepaid models generate fast cash flow. Yet risk control is extremely challenging. Claude recently intensified KYC checks and account bans; OpenAI has patched many “zero-cost” loopholes. Meanwhile, service instability leads to high after-sales costs, compounded by fierce competition—many transit hubs now face declining volume and pricing.
Thus, this industry resembles a short-term, high-turnover, low-stability, high-risk window—hard to transform into a sustainable, stable, long-term venture.
2. Why Is “Token Export” Reemerging?
If “token import” exploits price gaps in overseas models, “token export” leverages the cost-efficiency advantage of domestic models, packaging them for resale to overseas users—a reverse export path.
Domestic models offer significant pricing advantages. Using early 2026 data as reference, Qwen3.5’s cost is as low as 0.8 CNY per million tokens (~0.11 USD)—1/18th of Gemini 3 Pro’s price and over 27 times cheaper than Claude Sonnet 4.6’s $3 input rate. GLM-5 outperforms Gemini 3 Pro on programming benchmarks and approaches Claude Opus 4.5’s performance, yet its API price is merely a fraction of the latter’s.
These domestic models have limited availability overseas due to registration barriers, payment restrictions, language interfaces, and information asymmetry among overseas developers regarding domestic model capabilities—creating invisible entry barriers.
Consequently, some transit hubs purchase model API quotas in bulk in China using RMB, expose OpenAI-compatible interfaces via protocol translation layers, and sell to overseas developers and startups using USDT/USDC—with substantial profit margins.
For example, Alibaba Cloud’s BaiLian Coding Plan bundles Qwen3.5, GLM-5, MiniMax M2.5, and Kimi K2.5. New users get 18,000 requests for just 7.9 CNY in their first month—equivalent to selling at a dollar-denominated rate abroad, achieving profit margins exceeding 200%.
From a pure business logic standpoint, this clearly offers room for profit.
But long-term, it still faces the same unavoidable challenge: sustainability and compliance.
3. Is This Path Stable?
No, it is not stable. Recently, MiniMax announced tightening regulations on third-party transit hubs due to some resellers cutting corners, damaging MiniMax’s reputation. Beyond the legal risks—such as potential criminal liability if token sources involve fraud or theft—users employing transit tokens may leak data or misuse them for malicious purposes, exposing the seller to unintended liabilities.
Therefore, the real question isn’t whether you can make money—but whether the profits can offset the systemic risks ahead.
Five: How Can Ordinary Users Identify Transit Hub Risks?
In a market full of mixed-quality transit hubs, choosing reliable services is crucial.
Due to widespread model substitution and adulteration, users can adopt detection techniques:
Recommended: “ping + self-report model” command consistency test
Prompt Example (copy and send directly to the hub):
Always say 'pong' exactly, and tell me which model series you belong to, preferably specifying the exact version. Reply in Chinese.
User Input: ping
True Model Characteristics:
Fake Model / Adulterated Features:
Reference @billtheinvestor’s detection method: https://x.com/billtheinvestor/status/2029727243778588792
0.01 Temperature Sorting Test: Input “5, 15, 77, 19, 53, 54” and ask the AI to sort them or identify the maximum. Genuine Claude almost always outputs 77 consistently; true GPT-4o-latest often returns 162. If results fluctuate wildly across 10 consecutive trials, it’s likely a fake model.
Additionally, users can leverage third-party transit hub detection websites to assess their token’s “purity”—though this risks exposing keys in plaintext. The safest option remains official channels.
It must be emphasized:
Even with detection skills, users cannot fully avoid risks. Many risks remain invisible to average users.
Final Thoughts
Transit hubs are not the ultimate solution in the AI era—they are merely a temporary arbitrage window arising from misalignments in global model capabilities, pricing mechanisms, payment conditions, and access permissions.
For ordinary users, they may serve as a low-cost gateway to elite models. But for developers, teams, and entrepreneurs, the true cost is never the token itself—but the underlying stability, security, compliance, and trustworthiness.
Low prices can be copied; interface compatibility can be replicated. What cannot be easily copied is long-term reliability.
⚠ Reminder: If ordinary users wish to experiment, limit use to non-sensitive, non-critical scenarios—never input core data, trade secrets, or personal privacy. Developers should prioritize official APIs or officially maintained proxies to ensure stability and compliance. Entrepreneurs considering entry must establish clear exit strategies upfront to avoid getting trapped in gray zones.
Disclaimer: This article presents observational analysis of industry trends and public information for educational purposes only. It does not constitute any form of investment advice, entrepreneurial guidance, commercial recommendation, or API usage instruction.
Author: Shouyi, Denise | Biteye Content Team
Source: DeepChao TechFlow
Disclaimer: Contains third-party opinions, does not constitute financial advice
Which One Is Right for You: OpenClaw or Hermes?
04-26
Prompts Cannot Salvage Mediocre AI Writing
04-26
Xchat is officially live—after the review, words fail to express.
04-25
GPT Images 2.0 Comprehensive Guide: From Prompts to Full Workflow
04-24
Lobster Is History? Sorting Through Hermes Agent Tools That Can Scale Your Output 100x
04-13
10 Survival Rules for Ordinary People in the AI Era
04-08
The Golden Window for AI Entrepreneurship Has Only 12 Months Left
04-03


